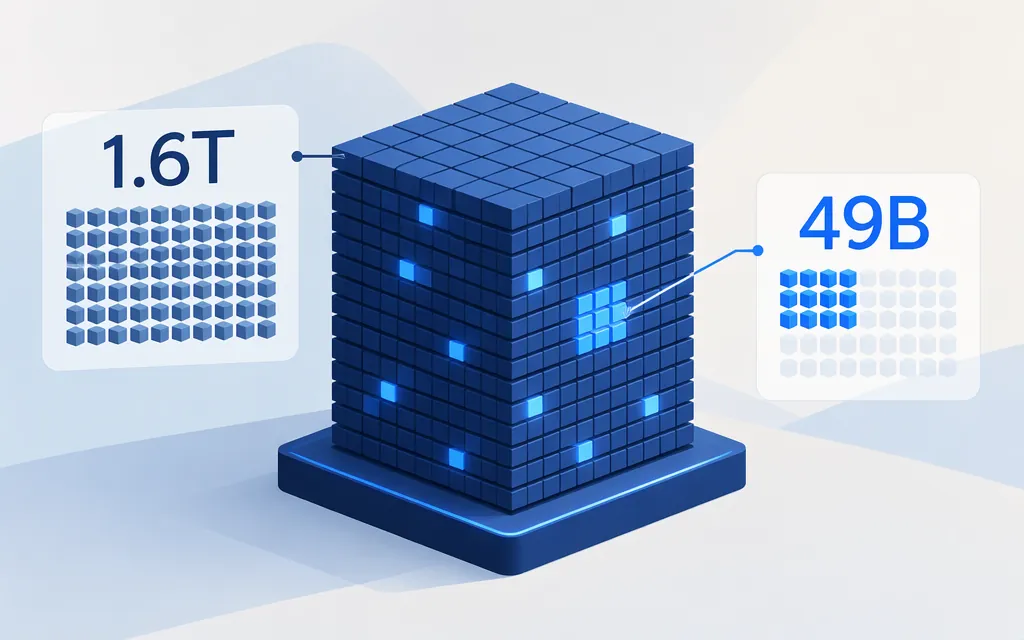
DeepSeek’s V4 model card lists DeepSeek-V4-Pro at 1.6 trillion total parameters and 49 billion activated parameters. It also lists a 1-million-token context length. These are model specifications, not API generation settings. For production, DeepSeek’s current API pricing documentation lists deepseek-v4-pro as model version DeepSeek-V4-Pro-0813, with a maximum output of 384K tokens and published token rates. (Hugging Face)
DeepSeek V4 Pro parameter count
| Specification | Published figure | What it describes |
|---|---|---|
| Total parameters | 1.6T | V4-Pro model weights |
| Activated parameters | 49B | Activated-parameter figure listed for V4-Pro |
| Model-card context length | 1M tokens | Model-card specification; API limits are listed separately |
| Weight precision | FP4 + FP8 mixed | V4-Pro model-card entry; V4-Pro-Base is listed separately as FP8 mixed |
The model card identifies V4-Pro as a mixture-of-experts (MoE) model. In that context, total refers to the full parameter count, while activated is the separate, smaller figure the model card reports for V4-Pro. Keep the variant attached to the figures: the card lists V4-Pro and V4-Pro-Base as separate entries. (Hugging Face)
A common mix-up is to assign V4.1-Flash’s figures to V4-Pro. DeepSeek describes V4.1-Flash as a 552B-parameter MoE, with 8B active for input and 16B active for output. Those are Flash figures, not Pro’s. (DeepSeek)
What the parameter count means for model selection
The 1.6T total count describes model scale; the 49B activated count is a distinct model-card figure. Neither number alone establishes API latency, throughput, cost, or quality for your particular workload.
Keep these three things separate:
- Model size: V4-Pro’s model card lists 1.6T total and 49B activated parameters.
- Request settings: Options such as reasoning effort configure a call; they do not change the model’s published parameter count.
- Served API version: The API model name and its currently documented version determine what DeepSeek says the API serves.
DeepSeek’s GA announcement documents low, high, and max reasoning-effort options for V4-Pro and V4-Flash. It describes low for simple tasks, high for everyday agent workflows, and max for complex tasks. These are request-level controls, not parameter-count options. (DeepSeek API Docs)
Production API status and rates
DeepSeek’s September 9, 2026 announcement said requests using deepseek-v4-pro would route to V4.1-Flash at Flash rates beginning September 14, 2026 at 04:00 UTC, until V4.1-Pro launched. That was a dated, conditional routing announcement. (DeepSeek)
DeepSeek’s current API documentation lists deepseek-v4-pro as DeepSeek-V4-Pro-0813 and publishes Pro-specific rates. This is the currently documented model mapping and billing information; the documentation does not independently report a live backend test or explicitly confirm whether V4.1-Pro has launched. The published mapping and rates are therefore more useful for current API selection than treating the September redirect announcement as an unconditional, still-current rule. (DeepSeek API Docs)
The API documentation lists a 1M-token context length, 384K maximum output, and no vision support for deepseek-v4-pro. Its listed rates per 1 million tokens are: (DeepSeek API Docs)
| Token type | Off-peak | Peak |
|---|---|---|
| Input, cache hit | $0.022 | $0.044 |
| Input, cache miss | $0.66 | $1.32 |
| Output | $1.98 | $3.96 |
DeepSeek’s pricing page says off-peak rates are half of peak rates. For the pricing table that lists deepseek-v4-pro, peak hours are 01:00–04:00 and 06:00–10:00 UTC, Monday through Friday, excluding Chinese public holidays. All other hours are off-peak, including weekends and Chinese public holidays in full. Pricing page reviewed November 10, 2026; check the live page when estimating spend because prices may change. (DeepSeek API Docs: Models & Pricing)
Bottom line
For the DeepSeek-V4-Pro model-card entry, the published figures are 1.6T total parameters and 49B activated parameters. For DeepSeek’s production API, the current docs list deepseek-v4-pro as DeepSeek-V4-Pro-0813, with a 1M-token context, 384K maximum output, no vision support, and the token rates shown above. Keep those API specifications distinct from model-size figures, and treat the September 2026 V4.1-Flash routing announcement as dated and conditional—not as proof of current routing by itself.