GLM-4.6 size, answered
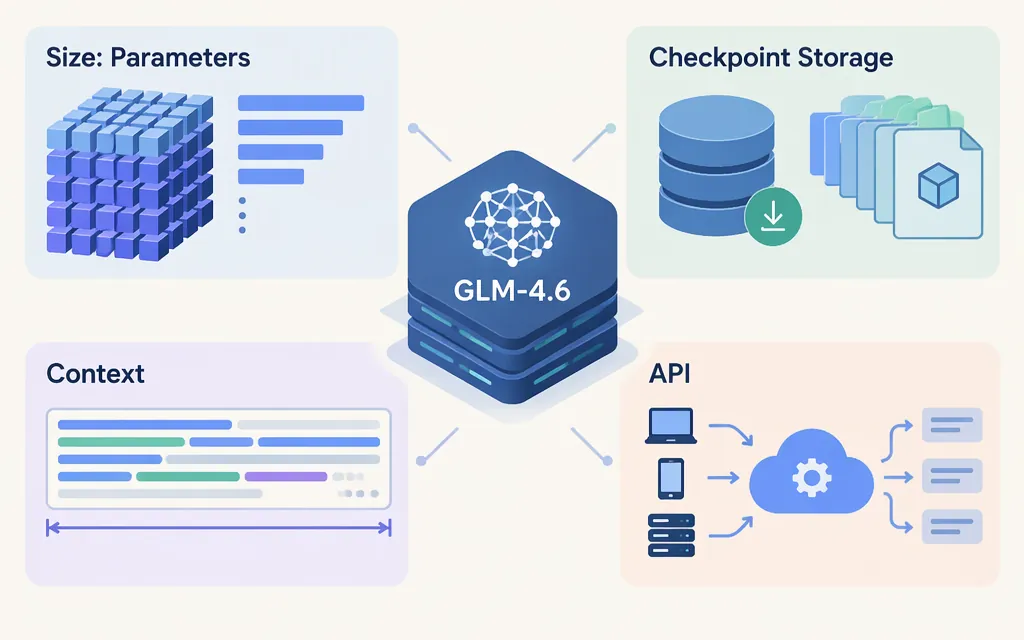
“GLM-4.6 size” can refer to several different things. The available figures are 357 billion parameters, a Hugging Face main repository display of 714 GB, and a 200K-token context window. These measure different things: parameters describe the model, gigabytes describe a repository listing, and tokens describe the context limit. None of these figures, by itself, specifies the VRAM or RAM needed for a particular deployment. (Hugging Face model page)
For hosted use, Z.AI’s developer documentation lists GLM-4.6 under the API model ID glm-4.6. It reports a 200K context length and a maximum output of 128K tokens. This establishes a documented Z.AI API option, not availability through TokenForge or another provider. (Z.AI migration guide)
What each GLM-4.6 size figure means
| Measure | Supported figure | What it tells you—and what it doesn’t |
|---|---|---|
| Parameters | 357B | Hugging Face lists the model size as 357B parameters. This is not a memory requirement. (Hugging Face model page) |
| Repository listing | 714 GB | The captured Hugging Face main-branch listing displays 714 GB and identifies a 92-shard safetensors sequence. Treat 714 GB as the page’s displayed repository size—not a verified weights-only download total or a VRAM estimate. The captured file listing is partial. |
| Context window | 200K tokens | Z.AI describes GLM-4.6’s context as expanded from 128K to 200K tokens. Context length is not parameter count or disk size. Z.AI also lists a maximum output of 128K tokens. (Z.AI GLM-4.6 documentation) |
| Runtime memory | Not established by these figures | The available figures do not establish a hardware configuration. Check deployment guidance for the specific weights, precision or quantization, and serving setup you intend to use. |
The captured repository rows show why the listing should not be mistaken for a complete file inventory: the first shard is listed at 2.2 GB, the next two at 650 MB each, and the fourth at 7.87 GB. These are examples of individual files, not a separately verified total. (Hugging Face repository files)
Is GLM-4.6 available through a production API?
Z.AI’s developer documentation lists GLM-4.6 for API use with the model ID glm-4.6. Its model page specifies text input and text output. This is evidence for Z.AI’s direct API, not a guarantee that another API gateway or reseller offers it. (Z.AI GLM-4.6 documentation, migration guide)
Published Z.AI API rates
Z.AI’s pricing page states that prices are in USD and lists model prices per 1 million tokens. For GLM-4.6, it shows $0.60 per million input tokens, $0.11 per million cached input tokens, and $2.20 per million output tokens. The table also labels cached-input storage as “Limited-time Free”; the page text retrieved here does not specify the promotion’s eligibility or end date, so confirm those terms before budgeting. (Z.AI pricing)
For illustration, 1 million uncached input tokens and 100,000 output tokens spread across multiple requests would cost $0.82 at those listed rates: $0.60 for input plus $0.22 for output. This is an aggregate estimate, not a single-request example; each request must fit the provider’s applicable limits. The estimate assumes all input is billed at the uncached rate and excludes any other charges or conditions.
Quick production-fit check
For a text-in, text-out workload, Z.AI’s direct API is a candidate if its published limits and behavior fit your requests. Z.AI lists a 200K context length and 128K maximum output, but the cited documentation excerpts do not clarify whether the context figure includes generated output or specify a separate maximum input. So don’t treat the two maxima as independently additive: confirm with Z.AI that your planned input and output fit the applicable request budget. Test representative prompts and integrations for your own performance and latency requirements; published limits do not guarantee results for a particular workload.
Bottom line: For parameter count, the listed figure is 357B. For the Hugging Face repository display, it is 714 GB for main—not a hardware recommendation. For context, the published figure is 200K tokens. Z.AI documents a direct API model ID and token-based rates; confirm request-budget interpretation and promotional terms with the provider, and verify other providers’ availability and pricing separately.
Sources
zai-org/GLM-4.6 — Hugging Face model page
zai-org/GLM-4.6 — Hugging Face repository files
GLM-4.6 — Z.AI developer documentation