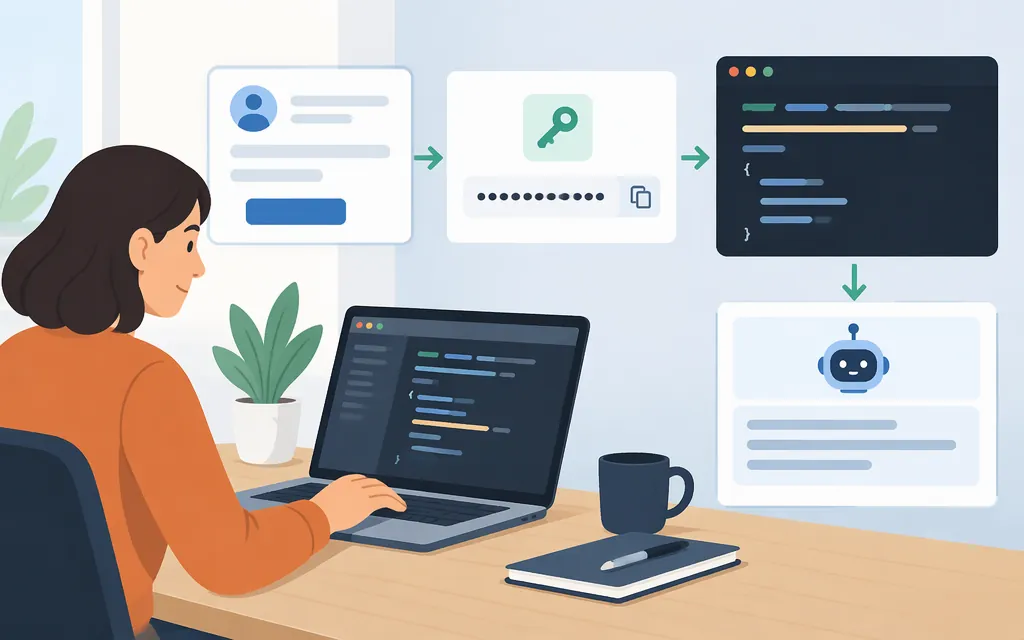
To use Grok in an application, create an API key in the xAI Console, store it as a secret, and send it as a Bearer token to the xAI API. For a new text-generation integration, xAI’s documentation recommends the Responses API at https://api.x.ai/v1/responses. The example below uses grok-4.7, which the model guide lists for general text and code tasks. This guide covers the developer API—not the consumer Grok app or a third-party connector. (Official quickstart)
1. Create an API key and set it up safely
- Sign up or sign in at the xAI Console and add credits to the team that will use the API.
- Create an API key from the Console’s API Keys page. Copy it when it is displayed; the full key is not shown again.
- Store it in a server-side environment variable or secrets manager—not in browser code, a public repository, or a chat message.
The API authenticates inference requests with Authorization: Bearer <API key>. Keep the credential on your server so people using your application cannot retrieve it from client-side code. The API Reference distinguishes the inference API from the separate Management API, which uses its own management key. (API Reference)
For a local shell session, set the variable before running the request:
export XAI_API_KEY='your-api-key'
API keys and API usage are managed through the developer Console; this is separate from using Grok in the consumer app at grok.com. (xAI Console)
2. Send a minimal test request
This follows the official quickstart’s curl pattern, using the Responses API and grok-4.7. It is a documented example, not a report of a request executed for this article. (Official quickstart)
curl https://api.x.ai/v1/responses -H "Authorization: Bearer $XAI_API_KEY" -H "Content-Type: application/json" -d '{"model":"grok-4.7","input":"Reply with the word ok."}'
A successful request returns an HTTP success response with JSON. The Responses API reference describes the response as containing an output array; the official OpenAI Python SDK example exposes generated text as response.output_text. Use the response shape for the SDK or endpoint you call rather than assuming every interface returns the same fields. (Responses API reference)
If a request fails, check the error message and status code against the official debugging guide. In particular, check key and team permissions for a 403, verify the model ID and URL for a 404, and consult your assigned limits for a 429.
3. Choose the API and model that fit the job
For text generation, reasoning, or tool use, use the Responses API for a new integration. xAI labels Chat Completions as deprecated and legacy. If you already use Chat Completions, consult the official migration guidance before changing request fields or response handling. (Responses API reference)
For general text and code, the model guide recommends grok-4.7 and lists a 500,000-token context window. Image, video, and voice tasks may use dedicated models and APIs; check the relevant model and endpoint documentation for supported inputs and parameters rather than treating product announcements or visual labels as API specifications. (Model guide)
4. Check cost, limits, and data handling before production
The model guide lists grok-4.7 at $2 per 1 million input tokens and $6 per 1 million output tokens among its rates. It also describes different pricing for requests above the 200,000-token context threshold, but the available excerpt does not establish exactly how that threshold applies to each token category. Treat these figures as a reference, not a complete estimate: check the current model pricing before budgeting, including cached-input and long-context rates.
Before launch, also check:
- Key permissions: Restrict a production key to the endpoints and models the application needs, where those permissions are available. The Management API documentation describes endpoint- and model-level permissions. (Accounts and authorization)
- Your actual rate limits: xAI sets per-model limits by team tier. Check your team’s current limits on the Console’s Models page; do not use an unconfirmed quota figure for capacity planning. A spending tier is not itself a request or token quota. (Rate-limit guide)
- Spend controls: Review API spend settings in the Console under Billing before launch. The billing guide describes the available credit and invoice controls; check the Console for the settings currently available to your team.
- Usage tracking: The cost-tracking guide says inference responses include a
cost_in_usd_ticksfield in the usage object. Consult the documentation for how to interpret it. (Cost tracking) - Data retention: The security FAQ states that, by default, API requests and responses are stored encrypted at rest for 30 days. Confirm the current training-use policy, retention options, and feature limitations in the security FAQ against your application’s data requirements.
- Billing: API usage and billing are managed through the developer Console, separately from the consumer Grok app. Check the API billing FAQ for current billing details.
Official references
Start with the official quickstart, then use the REST API reference, model guide, rate-limit guide, debugging guide, and security FAQ for implementation details that can change.