MiniMax M3 model size: the short answer
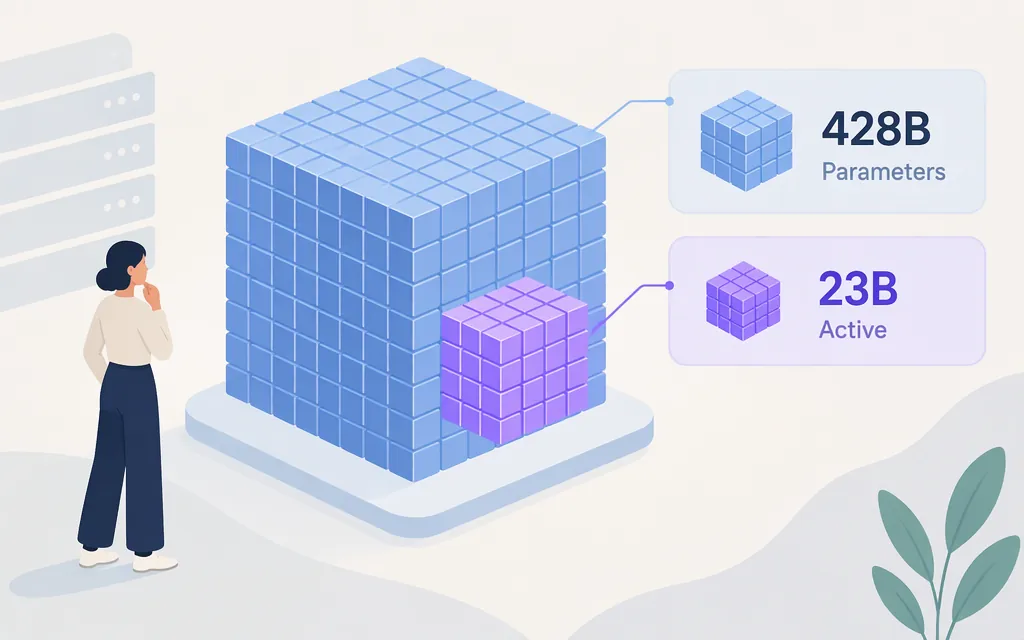
MiniMax M3 has approximately 428 billion total parameters, with approximately 23 billion activated per token. It is a mixture-of-experts (MoE) model: the active-parameter figure describes the portion engaged for a token, not the model’s total stored weights. So if you mean parameter count, the answer is about 428B total / 23B active—not “1M.” The million-token figure refers to context length. (huggingface.co)
For someone using a hosted API, parameter count usually isn’t a hardware-sizing requirement: the provider runs the model. If you plan to self-host, the downloaded artifact and its precision matter too. MiniMax’s self-hosting guide gives one specific reference point: an experimental setup using an MXFP8 weight repository of approximately 444 GB. That is an artifact size for that documented configuration—not a universal M3 file size, and not the amount of GPU memory the model requires. (platform.minimax.io)
Parameters, context and output are different measurements
| Measure | What it tells you | MiniMax M3 figure in current MiniMax documentation |
|---|---|---|
| Total parameters | The model’s overall parameter count | Approximately 428B |
| Active parameters | Parameters activated per token in the MoE model | Approximately 23B |
| Context window | The total token capacity for a request | 1,000,000 tokens |
| Maximum output | How many tokens a response can generate | The API overview says its maximum-token count covers input and output combined; check the chosen API route’s request limits rather than treating 1M as output capacity. |
MiniMax’s API overview lists M3’s context window as 1,000,000 tokens and clarifies that the maximum token count refers to total input and output. In practice, a request with a long prompt leaves less room within that total for generated output. (platform.minimax.io)
This also explains why older listings can be confusing. A Fireworks launch article described under-500K support at launch and a 1M window as forthcoming; a Kilo Code listing showed both 524,288 and 1M context figures. Those provider or platform statements don’t change the parameter count, and they shouldn’t override MiniMax’s current documentation when you’re checking MiniMax’s own API. Limits can still vary by provider or route, so confirm the documentation for the endpoint you intend to use. (huggingface.co)
What the size means for a production API choice
If you’re calling a hosted API: The 428B total parameter count does not tell you the API’s latency, price, throughput, or request limit. Use the provider’s documented model ID and endpoint, then test your own workload for response quality, latency, input/output usage, and required modalities. MiniMax currently lists both M3 and M3.1-Flash in its API model documentation; choose based on the exact model and capabilities your application needs, not parameter count alone. (platform.minimax.io)
If you’re choosing between long-context and ordinary requests: M3’s 1M-token context may be relevant for workloads involving very long documents, codebases, or multi-step agent sessions. But a larger context limit does not mean every request needs to use it: measure typical prompt length and output needs, and check how the selected provider bills those tokens. The sources reviewed here do not establish current, comparable API prices, so don’t rely on older relative-price statements to estimate today’s bill.
If you’re self-hosting: Don’t size a server from “23B active parameters” alone. The full weights must be available to the deployment, and storage, GPU memory, precision, serving software, and workload all matter. MiniMax labels its M3 self-hosting baseline experimental; the cited MXFP8 configuration uses 8 NVIDIA B200 GPUs and lists approximately 444 GB for the weights. Treat that as a specific documented reference, not a general minimum or a production guarantee. (platform.minimax.io)
Bottom line
For “MiniMax M3 model size,” use about 428B total parameters, with about 23B active per token. Keep that separate from the 1M-token context window. For hosted API selection, verify the exact model, route, limits, and current pricing with your provider; for self-hosting, use artifact- and configuration-specific hardware information rather than the active-parameter count.
Sources
MiniMaxAI/MiniMax-M3 model card
Self-host MiniMax-M3 — MiniMax API Docs
API Overview — MiniMax API Docs