Does NVIDIA offer a Kimi K2.5 API?
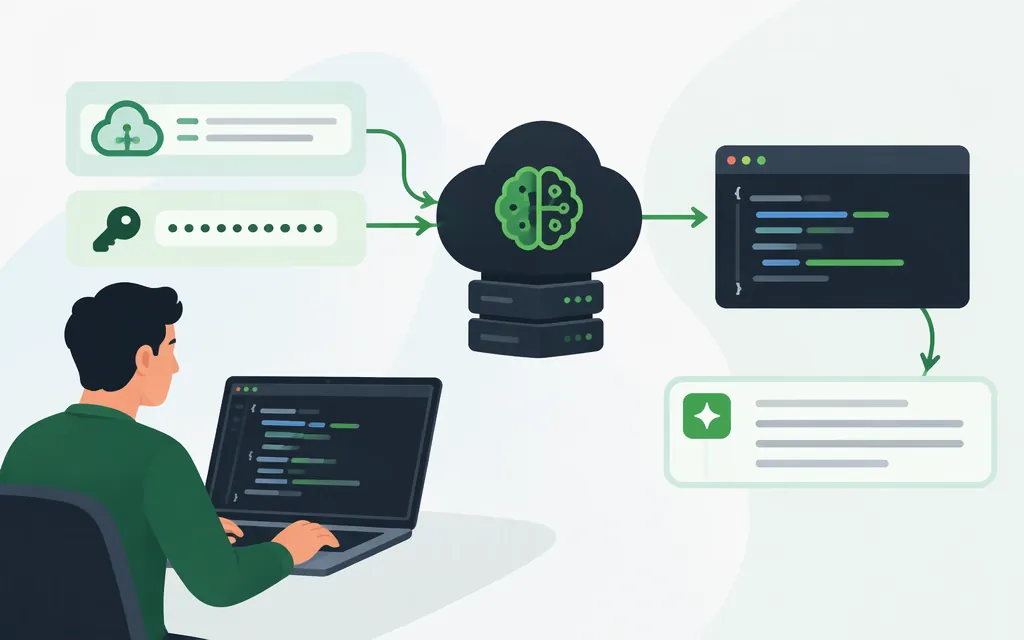
Yes. NVIDIA documents a hosted Kimi K2.5 chat-completions endpoint. The URL is https://integrate.api.nvidia.com/v1/chat/completions, and the model ID is moonshotai/kimi-k2.5. NVIDIA describes its hosted NIM endpoints as running on DGX Cloud. (docs.api.nvidia.com)
NVIDIA also documents running Kimi K2.5 in a local NIM container. That is a separate self-deployment route, not the hosted API request below. (docs.nvidia.com)
Make your first hosted API request
-
Get an NVIDIA API key. Open the Kimi K2.5 model page and select Get API Key. NVIDIA’s quickstart says to enter your email, then sign in or create an NVIDIA account and follow the on-screen steps. When the key appears, copy it and store it privately. (
docs.api.nvidia.com) -
Set the key in your shell:
export NVIDIA_API_KEY='YOUR_NVIDIA_API_KEY' -
Send a non-streaming text request:
curl --fail-with-body --silent --show-error \
  --request POST \
  'https://integrate.api.nvidia.com/v1/chat/completions' \
  --header "Authorization: Bearer ${NVIDIA_API_KEY}" \
  --header 'Content-Type: application/json' \
  --data '{
    "model": "moonshotai/kimi-k2.5",
    "messages": [
      {"role": "user", "content": "Reply with exactly: K2.5 API connected"}
    ],
    "max_tokens": 1024,
    "stream": false
  }'
The Kimi K2.5 reference documents the POST endpoint, model ID, messages, and max_tokens range of 1–32,768. It describes stream as returning partial message deltas when enabled. NVIDIA’s hosted API-key quickstart explains how to obtain the key; NVIDIA API examples use Bearer authorization. The 1,024-token budget avoids imposing a very short cap on a reasoning-capable model. The request has not been live-tested here. (docs.api.nvidia.com)
Check the result in two steps: first, confirm curl did not report an HTTP error. Then inspect the JSON assistant text at choices[0].message.content and check whether it is non-empty and useful. Treat the requested phrase as a prompt-level check, not a guarantee: exact wording is not assured. NVIDIA’s API reference documents the request parameters, but the retrieved reference does not show a Kimi-specific response example. A March 2026 NVIDIA forum post reported that some Kimi K2.5 requests returned HTTP 200 with blank or unusable content; that is a dated user report, not confirmation of current service behavior. (forums.developer.nvidia.com)
Access, deployment, and production considerations
- Prototype access: NVIDIA says developers can prototype with Kimi K2.5 on GPU-accelerated endpoints through the NVIDIA Developer Program. The model documentation says the hosted trial is governed by NVIDIA’s API Trial Terms. Do not treat prototype access as a production pricing commitment. (
developer.nvidia.com) - Price and quotas: The cited NVIDIA materials do not state a Kimi K2.5 production price per token or a specific quota. Check the applicable account terms before budgeting or relying on trial access in production.
- Multimodal requests: For image, video, or other non-text request formats, consult NVIDIA’s Kimi K2.5 request-format documentation rather than inferring a payload from the text-only example. (
docs.api.nvidia.com) - Self-hosted alternative: NVIDIA separately documents a local Kimi K2.5 NIM container and local chat-completions example. Its infrastructure and setup differ from the hosted API. (
docs.nvidia.com) - Keep versions distinct: Kimi K2.6 is a different model. Do not substitute its model ID, limits, or settings for Kimi K2.5.
For a first integration, use the hosted endpoint and model ID above, test with a small text request, and verify both HTTP status and the returned assistant content. Review the trial terms and your account’s access conditions before moving beyond prototyping.
Sources
Request response from the model — NVIDIA Kimi K2.5 API reference
API Catalog Quickstart Guide — NVIDIA
moonshotai / kimi-k2.5 — NVIDIA API documentation
Query the Kimi-K2.5 API — NVIDIA NIM documentation
Build with Kimi K2.5 Multimodal VLM Using NVIDIA GPU-Accelerated Endpoints
Moonshotai/kimi-k2.5 on Hosted Integrate returns success-shaped failures — NVIDIA Developer Forums