GPT-4o mini API pricing at a glance
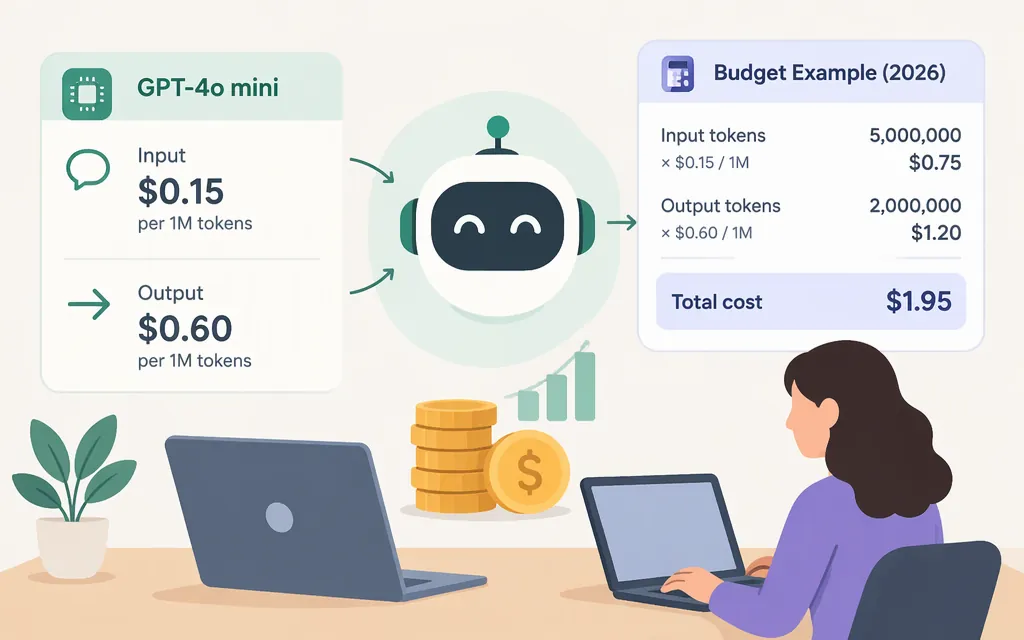
As of November 9, 2026, OpenAI’s API model page lists GPT-4o mini at $0.15 per 1 million input tokens and $0.60 per 1 million output tokens. It also lists cached input at $0.075 per 1 million tokens. These are API token rates, not a ChatGPT subscription price. (developers.openai.com)
| Token category | Listed price (USD per 1 million tokens) |
|---|---|
| Input | $0.15 |
| Cached input | $0.075 |
| Output | $0.60 |
The cached-input rate is half the listed regular input rate. Whether a request qualifies for cached-input pricing depends on the request and applicable caching rules; the budget example below assumes no cached tokens. These rates are for the general GPT-4o mini API model—not the separately named gpt-4o-mini-tts model.
Estimate a production text workload
Formula:
cost = (input tokens ÷ 1,000,000 × $0.15) + (output tokens ÷ 1,000,000 × $0.60)
Illustrative monthly example—not a forecast: Suppose an application makes 100,000 text-only requests in a month. If each request averages 1,000 billable input tokens and 300 output tokens, that is 100 million input tokens and 30 million output tokens:
- Input:
100 × $0.15 = $15 - Output:
30 × $0.60 = $18 - Estimated total: $33 for the month, or about $0.00033 per request.
This example uses the listed standard rates, assumes all input is billed at the regular input rate, and excludes image inputs, tools, other separately billed services, and any applicable taxes or account-specific charges. Replace the assumed token totals with your workload’s actual billable usage. OpenAI’s model page says tool-specific models can have a fee per tool call, so a tool-using workflow may need a separate line in its budget. (developers.openai.com)
Check production fit before building around it
OpenAI describes GPT-4o mini as accepting text and image inputs and producing text outputs, including Structured Outputs. The model page lists a 128,000-token context window and a 16,384-token maximum output. The estimate above is text-only; image requests should be costed from their applicable usage rather than treated as ordinary text-only prompts. (developers.openai.com)
Important lifecycle caveat: OpenAI’s model page labels GPT-4o mini as Deprecated. That is material for a new production deployment even though the page also lists its rates and capabilities. Before committing to the model, check the current API deprecation information and the model’s shutdown_date; OpenAI says that field can be checked through the List models endpoint. The documentation captured here does not establish a GPT-4o mini shutdown date. (developers.openai.com)
Bottom line: budget from the API’s separate input and output token counts—not from a single blended price. The official model page lists $0.15/$0.60 per million input/output tokens, plus $0.075 per million cached input tokens, but the deprecation label makes lifecycle status a key production decision alongside cost. (developers.openai.com)